Overview
A traffic sensor’s future readings can depend on nearby roads. Adding every sensor in the city can make the model search through many unrelated signals. This paper explores the middle ground by training on subsets of channels and combining predictions from different groupings.
Key Findings
The temperature in one part of a building may help predict the temperature next door. Bringing in every sensor from every floor can be expensive and may drown that relationship in irrelevant inputs. PMformer asks how much of the building a forecaster needs to see at once.
Train on part of the network at a time
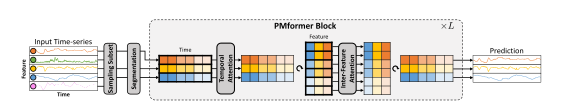
Univariate models process each series separately. A complete multivariate model can use information from every series. PMformer trains a Transformer on subsets of the available series so it can learn cross-series relationships without attending to the whole set at once. At inference, the authors try repeated random partitions and aggregate forecasts. This increases the chance that useful predictors appear in the same subset. The headline comparisons use three partitions, and the appendix reports strong average results with a single partition.
Table 3 varies the subset size within the same model family. Lower mean squared error is better. The selected results include one case where the partial model trails the single-series version.
| Dataset and horizon | Single series | Partial multivariate | All series |
|---|---|---|---|
| Weather, 96 | 0.141 | 0.142 | 0.146 |
| Electricity, 192 | 0.146 | 0.142 | 0.147 |
| Traffic, 192 | 0.388 | 0.370 | 0.383 |
| Traffic, 720 | 0.441 | 0.426 | 0.441 |
The Traffic and Electricity comparisons make the largest channel counts particularly interesting. The paper’s PAC-Bayes analysis links subset size to the effective number of training examples and the entropy of the learned distribution. The paper also studies missing features. The accuracy of random partitions still depends on how often they place informative series together and how much inference repetition a deployment can afford.
Make more than one pass through the neighborhood
The authors study both random sampling and random partitions during training. At inference, a fresh partition changes which series share a Transformer input. For a particular series , a simplified description of aggregation over forecasts is
This gives a predictor that can use different neighbors on different passes while controlling the width of any single pass. It introduces a separate decision about how many passes the forecasting budget can afford.
The useful group size varies
The subset-size comparison asks whether a gain comes from cross-series information or from giving every series the largest possible context. A small group can omit a relevant series. A large one can make the model expensive and include irrelevant inputs. The benchmark and appendix examine both the number of series per group and the cost of making more than one prediction. This is useful when a practitioner has many measurements but expects only some to move together.
Questions & Answers
The opening answers are simulated author responses based on the paper.
Q: Why use multiple partitions?
A: One partition may leave useful series in different groups. Repeating the partition gives the model additional combinations to use.
Q: Does the method require a known dependency graph?
A: The random grouping strategy can work without a graph. The paper’s attention-score-based grouping has higher error than random partitioning on Electricity and Traffic in Table 4. An available graph can serve as a separate baseline.
Q: When might random partitions miss a useful relationship?
A: A series can depend strongly on a rare partner that lands in a different subset. Drawing more partitions increases the opportunities to include useful partners and also adds work at inference. A single-series baseline is worth retaining, since the paper includes a Weather setting in which it performs slightly better than the selected multivariate setup.
Future Ideas
Forecast a building while sensors are offline
Use temperature and power readings from several buildings. Compare single-series, partial, and full models under matched inference latency. Simulate missing streams in contiguous blocks and hold out seasons and evaluate on channels seen in training. A separate study of unseen buildings would need a way to handle new feature identities. Report horizon-specific error and how often a missing neighbor causes a large miss.
Build a correlation-based grouping from the training period only and compare it with random groups after a seasonal or equipment change. Use a one-partition baseline and a fixed inference-latency budget to see whether additional partitions or better grouping buy the most accuracy.
Sources
Original abstract
When solving forecasting problems including multiple time-series features, existing approaches often fall into two extreme categories, depending on whether to utilize inter-feature information: univariate and complete-multivariate models. Unlike univariate cases which ignore the information, complete-multivariate models compute relationships among a complete set of features. However, despite the potential advantage of leveraging the additional information, complete-multivariate models sometimes underperform univariate ones. Therefore, our research aims to explore a middle ground between these two by introducing what we term Partial-Multivariate models where a neural network captures only partial relationships, that is, dependencies within subsets of all features. To this end, we propose PMformer, a Transformer-based partial-multivariate model, with its training algorithm. We demonstrate that PMformer outperforms various univariate and complete-multivariate models, providing a theoretical rationale and empirical analysis for its superiority. Additionally, by proposing an inference technique for PMformer, the forecasting accuracy is further enhanced. Finally, we highlight other advantages of PMformer: efficiency and robustness under missing features.