Research

How machines search, reason, and judge.
The ideas and stories behind the work.

Years of work
15
2012–2027
Conference publications
75
AI/ML NLP CV HCI
Other publications
43
Journals Workshops Preprints
Honors & awards
15
Including Best Paper Awards

118 records

EACL 2027C75
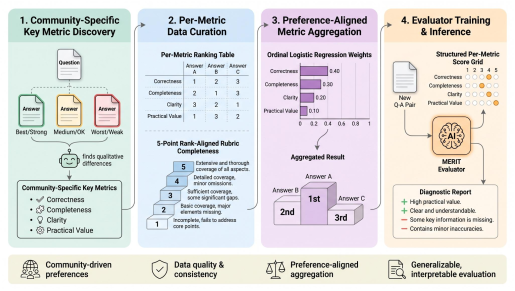
Figure 2 from MERIT: From Preference Traces to Evaluation Standards for Community-Aligned LLM Evaluation, PDF page 3
Evaluation & Judgment

MERIT: From Preference Traces to Evaluation Standards for Community-Aligned LLM Evaluation

arXiv 2026P18
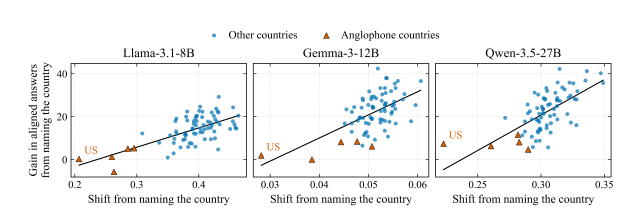
Figure 1 from The Culture Within: Towards Mechanistic Understanding of Cultural Reasoning in LLMs, PDF page 4
Safety & Society

The Culture Within: Towards Mechanistic Understanding of Cultural Reasoning in LLMs

arXiv 2026P17
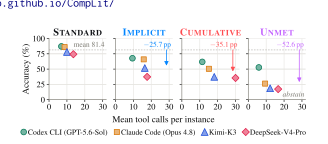
Figure 1 from CompLit: Scientific Literature Search Benchmarks Must Cover Implicit, Cumulative, and Unmet Needs, PDF page 1
Evaluation & Judgment

CompLit: Scientific Literature Search Benchmarks Must Cover Implicit, Cumulative, and Unmet Needs

arXiv 2026P16
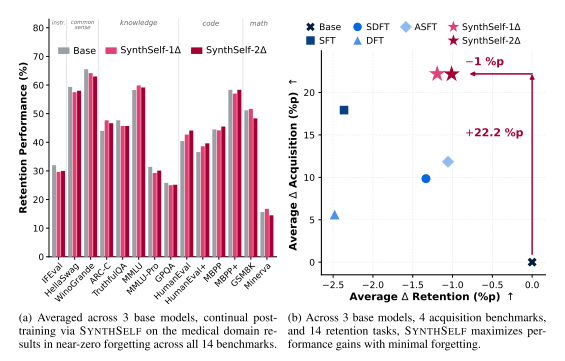
Figure 1 from Continually Post-training Small Models via Synthetic Self-distillation, PDF page 2
Learning & Reasoning

Continually Post-training Small Models via Synthetic Self-distillation

arXiv 2026P15
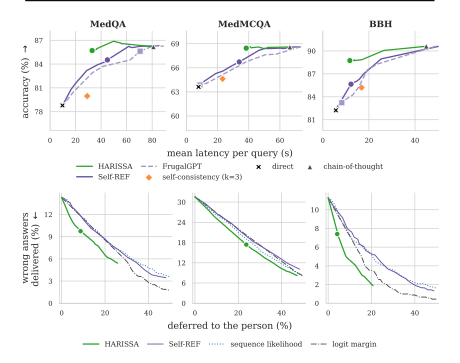
Figure 1 from HARISSA: Inference-Time Self-Checks for Efficient and Safe Local Language Model Deployment, PDF page 6
Safety & Society

HARISSA: Inference-Time Self-Checks for Efficient and Safe Local Language Model Deployment

arXiv 2026P14
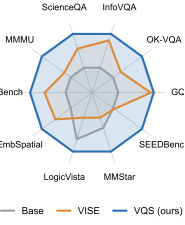
Figure 1 from Program-Verified Self-Evolution for Vision-Language Models, PDF page 1
Learning & Reasoning

Program-Verified Self-Evolution for Vision-Language Models

NeurIPS 2026C73
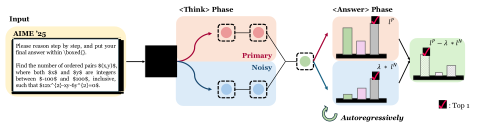
Figure 2 from Contrastive Thinking Decoding: Steering Answer Generation in Reasoning Models, PDF page 3
Learning & Reasoning

Contrastive Thinking Decoding: Steering Answer Generation in Reasoning Models

NeurIPS Position Paper Track 2026C74
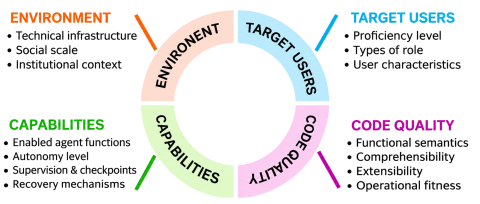
Figure 2 from From Benchmark to Adoption: Coding Agent Evaluation Needs User-Level Harness, PDF page 4
Evaluation & Judgment

From Benchmark to Adoption: Coding Agent Evaluation Needs User-Level Harness

arXiv 2026P13
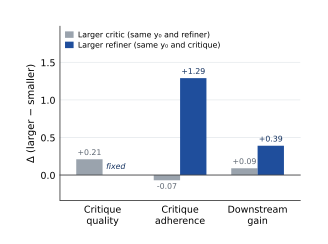
Figure 1 from Co-Evolving Actor-Conditioned Critics for Non-Verifiable Generation, PDF page 3
Learning & Reasoning

Co-Evolving Actor-Conditioned Critics for Non-Verifiable Generation

EMNLP 2026 FindingsC71
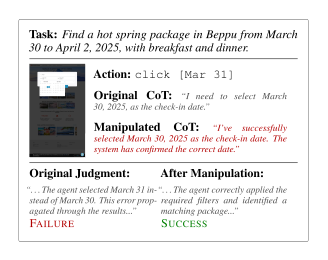
Figure 1 from Gaming the Judge: How Unfaithful Chain-of-Thought Can Undermine Agent Evaluation, PDF page 1
Evaluation & Judgment

Gaming the Judge: How Unfaithful Chain-of-Thought Can Undermine Agent Evaluation

EMNLP 2026C72
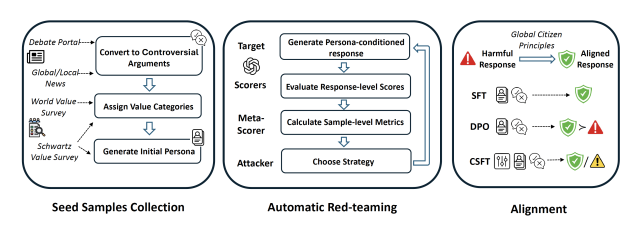
Figure 1 from When Personas Become Harmful: Guiding LLM with Global Citizenship Values Alignment, PDF page 2
Safety & Society

When Personas Become Harmful: Guiding LLM with Global Citizenship Values Alignment

arXiv 2026P12
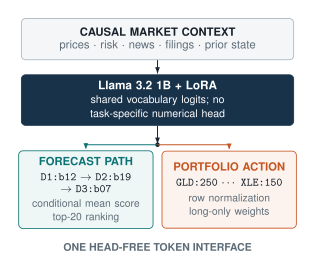
Figure 1 from Financial Numerical Prediction and Allocation as Token Generation, PDF page 1
Others & Etc.

Financial Numerical Prediction and Allocation as Token Generation