eclectics — Moontae Lee on AI research and leadership
AI RESEARCH & LEADERSHIPMake hard problems measurable
Make hard problems measurable
Build teams that solve and ship
WHAT AI CAN DO
FOCUS / RESEARCH
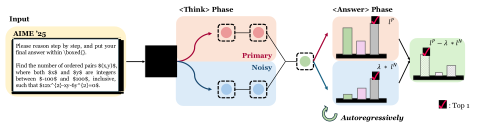
DEER
What makes a research report worth trusting?
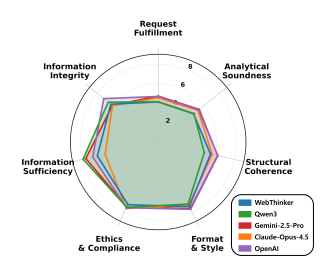
ICML 2026FIGURE FROM P.1
FOCUS / THOUGHTS
Double Helix of Intelligence (Part I)
The mathematics of keeping a generator and evaluator on course, from constrained initialization to game dynamics and mode selection.
RESEARCH ESSAYGENERATED FIGURE
RESEARCH, ON THE RECORD
SELECTED PAPERS
EMNLP 2026 FindingsC71
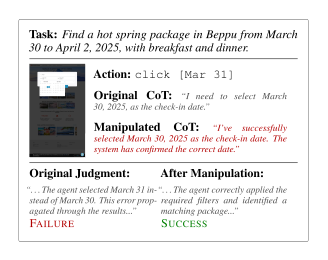
Gaming the Judge: How Unfaithful Chain-of-Thought Can Undermine Agent Evaluation
arXiv 2026P17
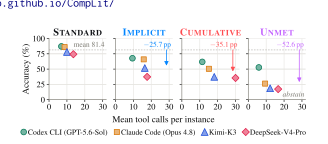
CompLit: Scientific Literature Search Benchmarks Must Cover Implicit, Cumulative, and Unmet Needs
NeurIPS 2025C58
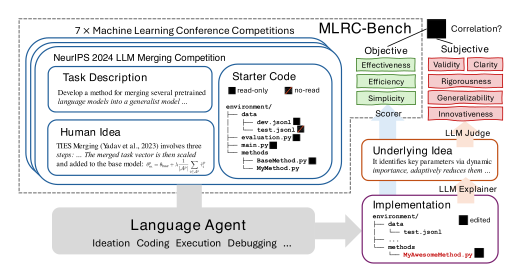
MLRC-Bench: Can Language Agents Solve Machine Learning Research Challenges?
NeurIPS 2023C25
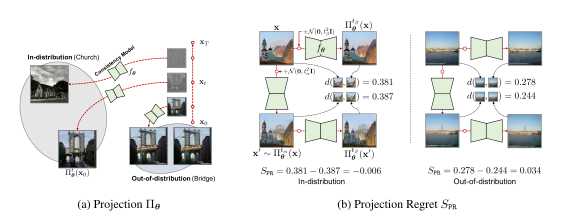
Projection Regret: Reducing Background Bias for Novelty Detection via Diffusion Models
ACL 2026C66
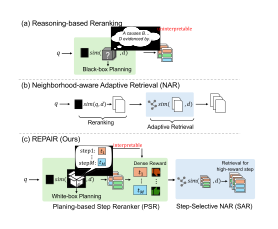
Adaptive Retrieval for Reasoning
NeurIPS Position Paper Track 2026C74
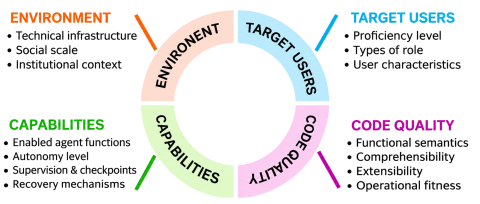
From Benchmark to Adoption: Coding Agent Evaluation Needs User-Level Harness
NAACL 2025C45
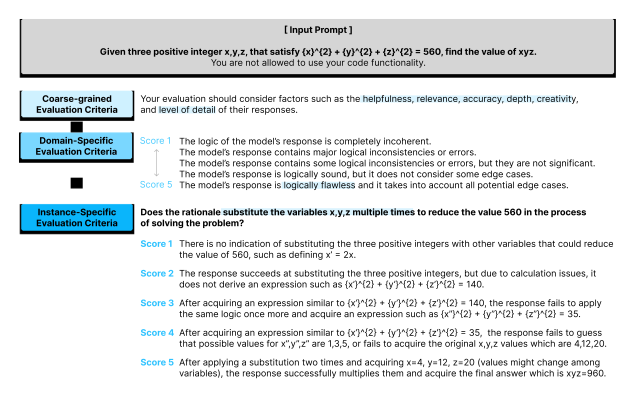
The BiGGen Bench: A Principled Benchmark for Fine-grained Evaluation of Language Models with Language Models
EMNLP 2024C43
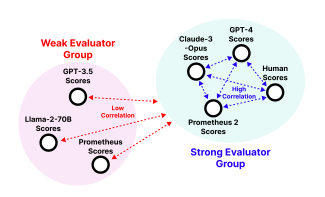
Prometheus 2: An Open Source Language Model Specialized in Evaluating Other Language Models
EACL 2027C75
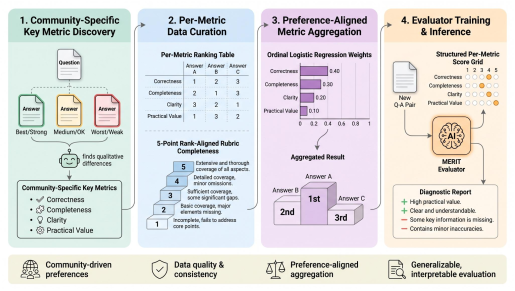
MERIT: From Preference Traces to Evaluation Standards for Community-Aligned LLM Evaluation
ACL 2026C67
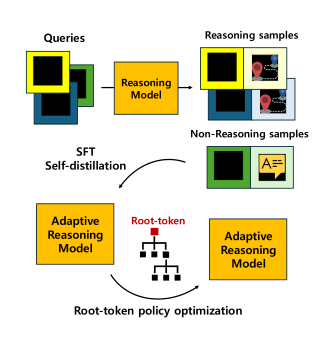
Efficiently Learning To Reason or Not to Reason: Root-token Policy Optimization for Adaptive Thinking
CoLLA 2024C37
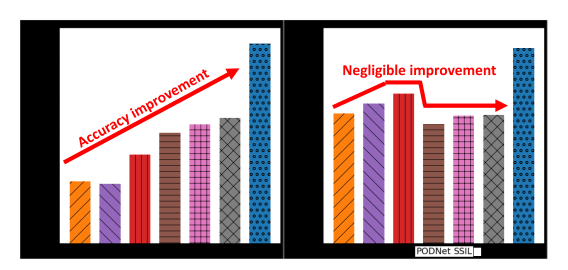
Towards More Diverse Evaluation of Class Incremental Learning: Representation Learning Perspective
arXiv 2026P13
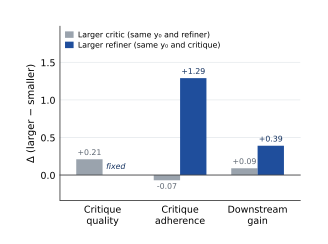
Co-Evolving Actor-Conditioned Critics for Non-Verifiable Generation
ACL 2024 FindingsC39
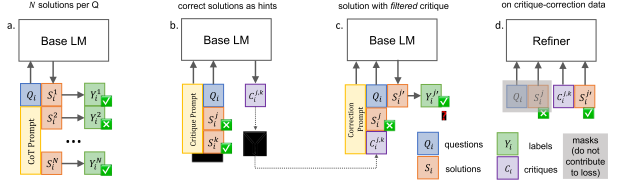
Small Language Models Need Strong Verifiers to Self-Correct Reasoning
arXiv 2026P12
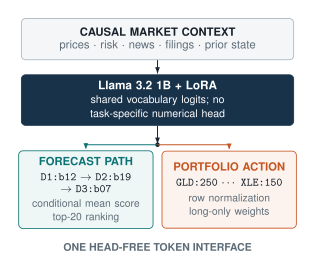
Financial Numerical Prediction and Allocation as Token Generation
ICML 2024C38
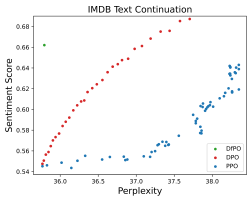
Degeneration-free Policy Optimization: RL Fine-Tuning for Language Models without Degeneration
NeurIPS 2026C73